> For the complete documentation index, see [llms.txt](https://docs.powermonitor.com.br/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.powermonitor.com.br/en/power-monitor/mapeamento/sessoes-spark.md).
# Spark Sessions
Follow, trigger and pause the collection of Spark (Livy) sessions of Lakehouses, Notebooks and Spark Job Definitions, which runs every 6 hours.
The **Spark Sessions** collection reads in Microsoft Fabric the **Spark (Livy) sessions** of **Lakehouses**, **Notebooks** and **Spark Job Definitions** in the monitored workspaces and keeps the history for 90 days. The indicators, charts and the list of sessions are in Monitoring; this screen shows the collection history and lets you trigger or pause it.
**How to access:** *Mapping › Operations › Spark Sessions*. Only **Administrators** can access the screen and the actions. On the data screen, all profiles see the **Collection** line with the date of the last run; the **View/manage collection →** link, which leads here, appears only for administrators.
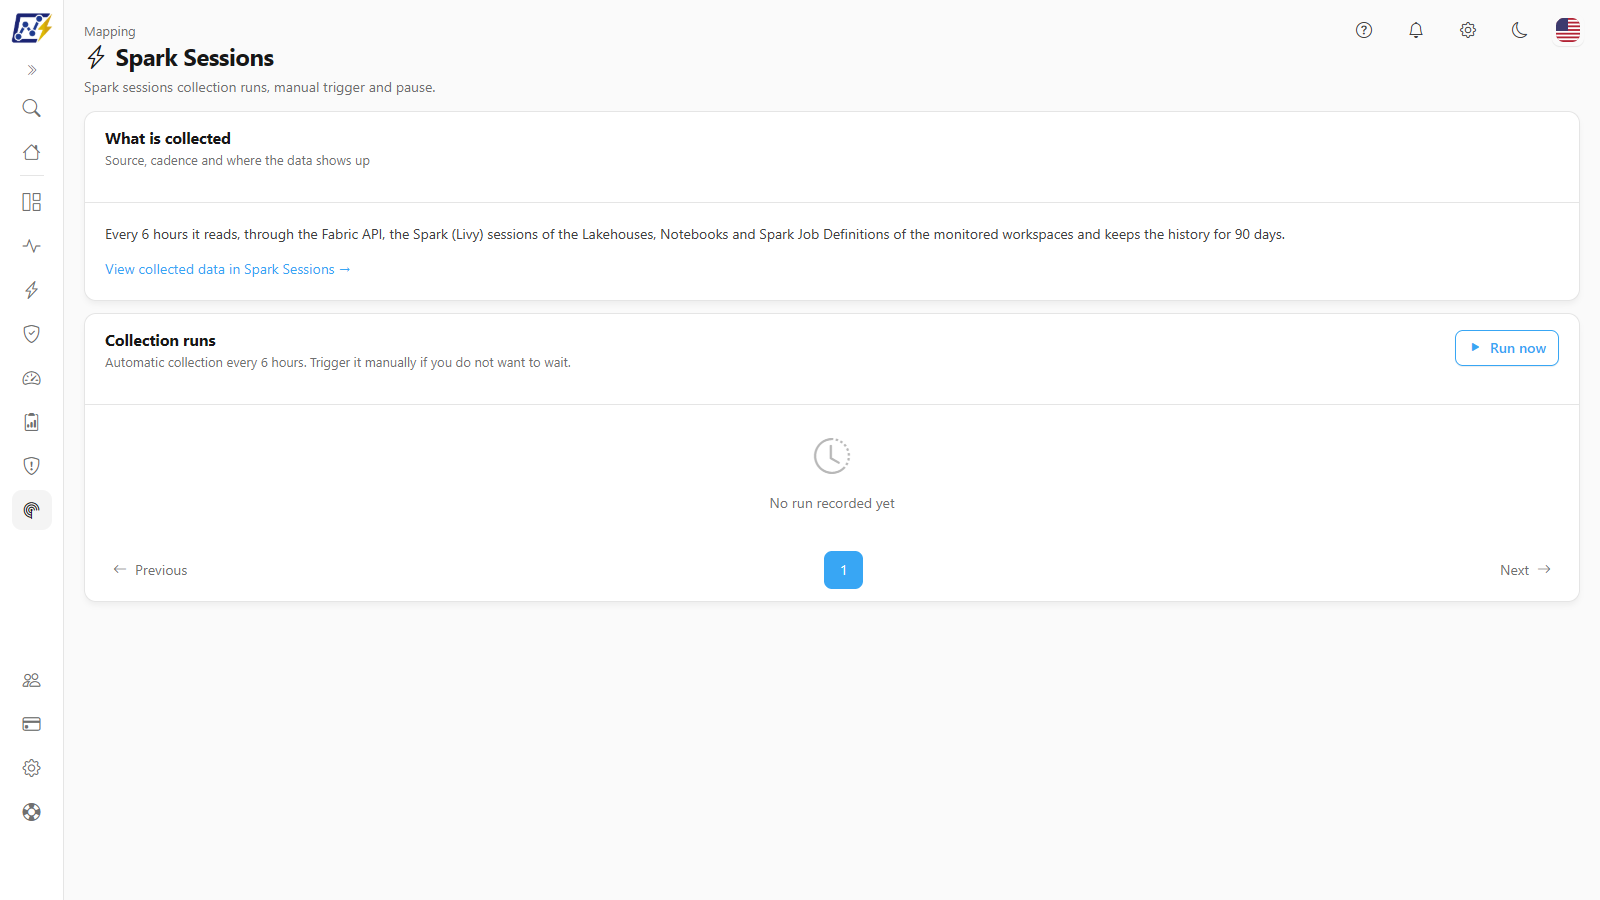
Spark Sessions
## What it is for
* Keep up to date the Spark session history used in [Monitoring › Spark Sessions](/en/power-monitor/monitoramento/sessoes-spark.md): queue time, run time, failures per day and the items that use the most sessions.
* Bring the collection forward when you have just run notebooks or jobs and want to see the result without waiting for the next 6 hours.
* Confirm that the collection is running and investigate items that could not be read.
## Screen components
The screen has a header (*Mapping* and the collection subtitle) and two cards.
### What is collected card
Describes the source, the cadence and the history kept (*Source, cadence and where the data shows up*) and has, at the bottom, the **View collected data in Spark Sessions →** link, which leads to the data screen.
### Collection runs card
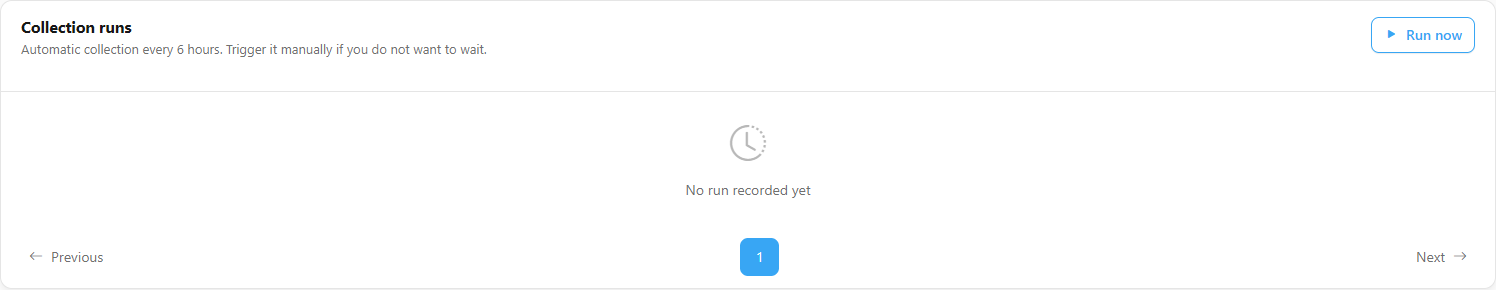
The **Collection runs** card (*Automatic collection every 6 hours. Trigger it manually if you do not want to wait.*) holds the buttons and the history.
Spark sessions collection runs
| Element | What it is for |
| ------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Run now** / **Resume** | Triggers a manual collection. When there is a **Paused** run, the button is renamed **Resume** and continues from where it stopped. It works even with the automatic collection turned off. |
| **Pause** | Appears only during a run in progress. The pause is cooperative: the notice **Pause requested: the run stops after the next processed item** appears and the run becomes **Paused** when it finishes the current item. |
| State badges | **Run in progress (n)** (with a progress bar), **Run paused** and, if automatic tracking ends, **Automatic refresh stopped. Reload the page to see the current status.** |
| Runs table | History from the most recent to the oldest, with an items-per-page selector and pagination. |
| **View failures** | Link in the **Failures** column that opens the **Failures for the {date} run** modal, with **Item**, **Reason** and **Detail**. |
Table columns:
| Column | Content |
| ----------------------------------------- | ------------------------------------------------------------------------------------------------- |
| **Trigger** | **Scheduled** or **Manual** (for manual runs, hover over the person icon to see who triggered it) |
| **Started** / **Finished** / **Duration** | Run times (no end and duration while it is active) |
| **Status** | **Running**, **Paused**, **Completed**, **Failed** or **Stuck** |
| **Items processed** | Number of items (Lakehouses, Notebooks and Spark Job Definitions) already covered by the run |
| **Failures** | Items that could not be read or saved; **View failures** link |
| **Error** | Icon with the run's general error message (hover over it) |
## Rules and behavior
* **Where the data comes from:** Fabric API (Livy sessions of each item), queried with the organization's Service Principal.
* **What is read:** Lakehouses, Notebooks and Spark Job Definitions already inventoried, not deleted, in **monitored** and active workspaces (see [Governance › Workspaces](/en/power-monitor/governanca/workspaces.md)). Personal workspaces are left out.
* **Frequency:** automatic, **every 6 hours**. Because it runs several times a day, this collection has no **Frequency** option (Daily, Weekly, Monthly). It can be turned off in [Settings › Monitoring](/en/power-monitor/configuracoes/monitoramento.md#scans-and-collections), **Scans and Collections** section, **Others** group, **Spark sessions** item (turned on by default). **Run now** works even with the switch turned off.
* **History:** sessions are kept for **90 days**. On the first read of an item, the sessions submitted in the last 7 days are included; on later reads, only what is new. Sessions that are still open are read again until they finish (for up to 7 days).
* **Limit per run:** up to **300 items** per run, starting with those never read and then those read the longest time ago. The rest go into the next runs, so a large environment is covered in a few rounds.
* **Items without access:** if the Service Principal cannot read the sessions of an item (no access to the workspace, or an item that no longer exists), the item is treated as **unavailable** and does **not** count as a failure.
* **Fabric request limit:** if Fabric throttles the calls, the run ends as **Failed** with a message saying that the Fabric request limit (429) was reached after n of m items and that the rest stay for the next run (the message is shown in Portuguese). What was already saved is kept.
* **Failures per item:** a failure on one item does not bring the collection down; it is counted in **Failures**, with the reason (could not read the item's Spark sessions, could not save them, or an unexpected failure while processing the item).
* **Stuck:** a run with no progress for **10 minutes** is closed as **Stuck**.
* **Concurrency:** there is only one active run (in progress or paused) per organization. When you try to trigger another one, *A run is already in progress for this organization.* appears.
* **Screen refresh:** while there is an active run, the table refreshes by itself every 20 seconds, for up to 30 minutes.
* **Prerequisite:** Service Principal configured and with access to the monitored workspaces. See [Additional Permissions › Add Service Principal to Workspaces](/en/power-monitor/configuracoes/permissoes-adicionais.md#add-service-principal-to-workspaces).
## Step by step
{% stepper %}
{% step %}
### Open the collection screen
Go to *Mapping › Operations › Spark Sessions* with an administrator account.
{% endstep %}
{% step %}
### Trigger the collection
In the **Collection runs** card, click **Run now**. There is no confirmation; the button shows **Running…** and the message *Run queued. The history updates when it starts.* appears. While the collection service has not picked up the run, the button shows **Queued** and the card says *Run queued, waiting to start…*; then the button changes to **In progress** and the bar shows the processed items (for example, *12 of 40*) and the estimated time left (*\~3 min left*). The screen tracks the run until it finishes, without reloading.
{% endstep %}
{% step %}
### Follow it
Watch the **Run in progress** badge and the new row in the history. If you need to stop it, click **Pause**; later use **Resume** to continue.
{% endstep %}
{% step %}
### Confirm the result
When it finishes, Power Monitor tells you that the collection completed (or that it finished with a failure). Open [Monitoring › Spark Sessions](/en/power-monitor/monitoramento/sessoes-spark.md) through the link in the **What is collected** card and check the data.
{% endstep %}
{% endstepper %}
## Frequently asked questions
I triggered the collection and the Monitoring screen did not change.
Wait for the run to show as **Completed** and reload the data screen. If the run finished with many unavailable items, the Service Principal probably has no access to the workspaces; see **Prerequisite** above.
Why does the collection take several runs to cover everything?
Each run reads at most 300 items, from the least recently read to the most recent. In environments with many items, full coverage takes a few 6-hour rounds.
Can I change the frequency to weekly or monthly?
No. The **Frequency** option only exists for collections that run once a day. You can turn the collection off in *Settings › Monitoring*.
The run ended as Failed with the request limit (429) message.
Fabric throttled the calls. Nothing is lost: the remaining items are read in the next run, within 6 hours, or in a new **Run now** later.
## Related pages
* [Monitoring › Spark Sessions](/en/power-monitor/monitoramento/sessoes-spark.md)
* [Settings › Monitoring](/en/power-monitor/configuracoes/monitoramento.md)
* [Additional Permissions](/en/power-monitor/configuracoes/permissoes-adicionais.md)
* [Governance › Workspaces](/en/power-monitor/governanca/workspaces.md)
* [Mapping](/en/power-monitor/mapeamento.md)
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://docs.powermonitor.com.br/en/power-monitor/mapeamento/sessoes-spark.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.